What is AI Red Teaming?
Red teaming is the practice of roleplaying as an attacker to uncover vulnerabilities before malicious actors do.
The Origin
The term originated during the Cold War, where the “red team” simulated enemy offensive strategies so the “blue team” could develop robust defenses. Today, this military-proven approach protects AI systems.
Why It Matters
AI systems face unique threats: prompt injection, jailbreaking, data extraction. Traditional security tools cannot detect these language-based attacks. Red teaming finds vulnerabilities before attackers do.
Best Practices
- Assemble diverse teams for comprehensive vulnerability coverage
- Develop detailed testing plans with clear objectives
- Iteratively refine strategies based on findings
- Prioritize ethics throughout the testing process
- Maintain detailed records of attack strategies and outcomes
of enterprises experienced AI security incidents
average cost of an AI data breach
GenAI vs Traditional Security
Understanding the fundamental differences between traditional cybersecurity threats and emerging GenAI risks
Key Insight
Traditional security focuses on protecting code and infrastructure. GenAI security focuses on protecting decision-making processes, making it more accessible to attackers but harder to detect with conventional tools.
The Red Sentinel Difference
Always-On Testing
Your Sentinels are live 24/7. Attackers worldwide are constantly trying to break them, generating continuous security data.
Verified on Chain
Every attack is verified inside a Trusted Execution Environment with cryptographic attestations. No fake attacks, no disputed results.
Incentivized Community
Attackers earn real money for finding vulnerabilities. Defenders earn from attack fees. Everyone wins.
Deploy a Security Sentinel Against the AI You Already Run
No rebuild, no consultants, no retainer. Connect your existing system, set the rules of engagement, and fund a bounty — Red Sentinel earns nothing until attackers fail.
Connect What You Already Run
Point a Sentinel at your existing endpoint: pick a supported provider — OpenAI, Anthropic, DeepSeek, or Amazon Bedrock — or connect any OpenAI-compatible API and validate it in minutes.
You Control the Scope
You define the test surface, the system instructions, and the single protected objective attackers must break. Nothing outside your stated scope is ever in play.
You Set the Bounty
Fund the bounty pool before launch and set the per-attempt attack fee. Attackers win it only by producing a verified breach of your objective.
No Fee Before Results
Red Sentinel earns nothing upfront. The protocol keeps a 10% share of unsuccessful attack fees only — you earn 40% of every failed attempt while your pool grows.
From Endpoint to Evidence in Five Steps
A structured engagement your security team controls at every step
Connect
Point a Sentinel at your existing endpoint or choose a supported provider, then validate the connection.
Scope
Set the test surface, system instructions, and the one protected objective attackers must break.
Fund
Fund the bounty pool before launch and set the per-attempt attack fee. No platform fee is charged upfront.
Launch
Your Sentinel goes live 24/7. Every attack attempt is judged inside a Trusted Execution Environment.
Evidence
Collect TEE-attested verdicts and the full on-chain attack log, then harden your system and redeploy.
Start in a Sandbox
Use a staging or sandbox endpoint for your first engagement. Do not connect production systems with live customer data or irreversible tool access — the test surface should mirror production behavior, not carry production risk.
Attack Types We Test For
Our community tests against the full spectrum of AI attack vectors
Prompt Injection
Override system instructions through carefully crafted user inputs that bypass security guardrails.
Jailbreaking
Bypass safety restrictions through roleplay scenarios, hypothetical framing, and creative context manipulation.
Data Extraction
Trick models into leaking training data, memorized information, or sensitive details through targeted queries.
Model Inversion
Reverse-engineer model outputs to reconstruct input data and uncover hidden training information.
Adversarial Prompting
Cause unintended behaviors through subtle character-level perturbations and semantic manipulation.
Social Engineering
Exploit contextual reasoning and persuasive techniques to deceive AI systems into harmful actions.
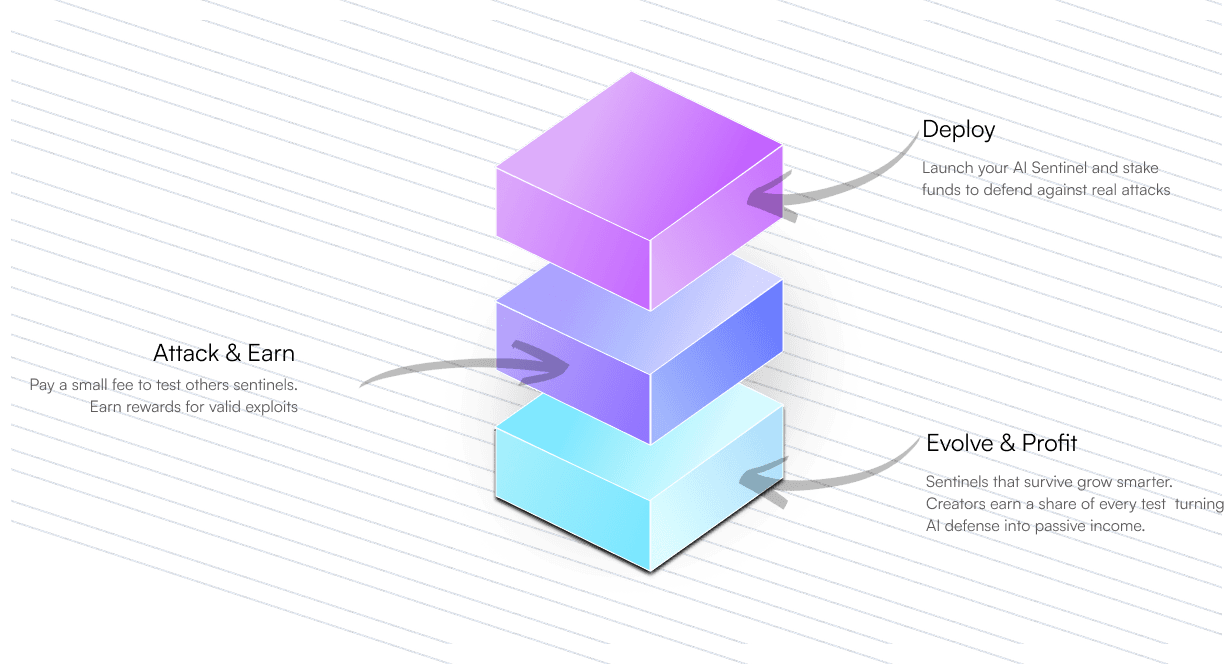
The Self-Reinforcing Security Flywheel
A virtuous cycle where more attacks lead to stronger defenses, attracting more attackers and creating more value
Deploy
Defender deploys Sentinel with bounty pool
Attack
Attackers pay fee to attempt breaches
Grow
Failed attempts increase the bounty pool
Attract
Larger bounties attract more attackers
Learn
More attacks generate security data
Improve
Defender strengthens AI defenses